What this topic helps you decide
Use this test when the central complaint involves restaurants, meetings, classrooms, vehicles or several speakers even though speech in quiet seems manageable. It can help quantify a signal-to-noise problem and establish a baseline for counseling or technology trials.
The useful question is not whether the technology or test is “good.” It is whether its measured function matches the person, the listening task and the environment. Separate screening, diagnosis, treatment, access and convenience because one product or result rarely performs all five roles.
How it works
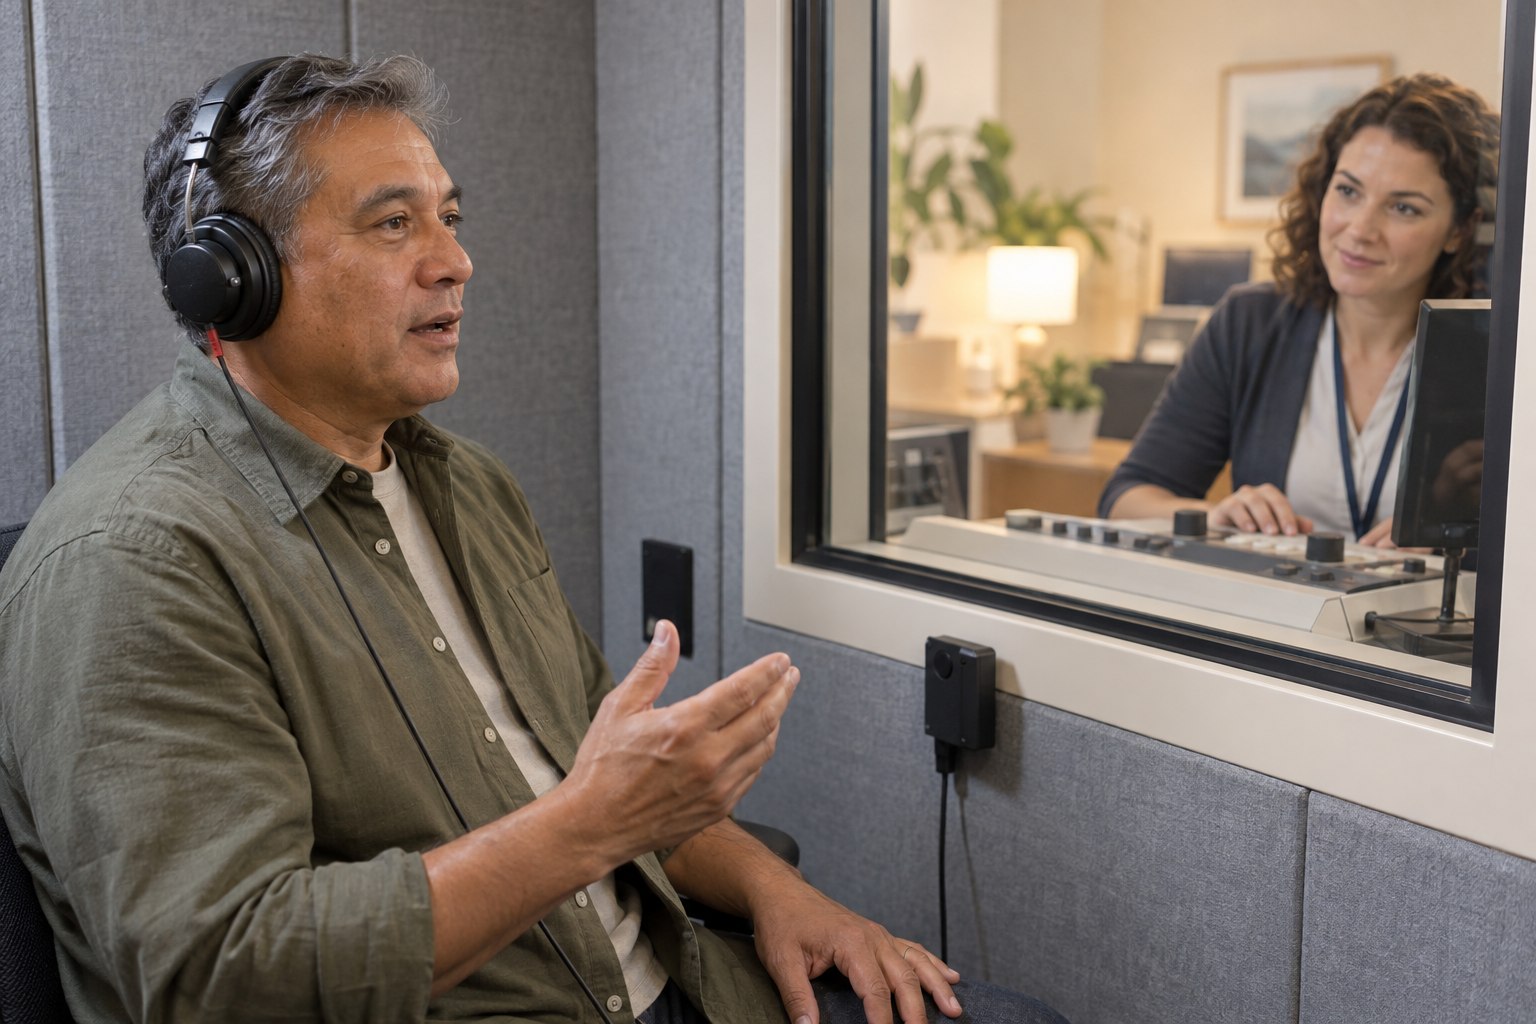
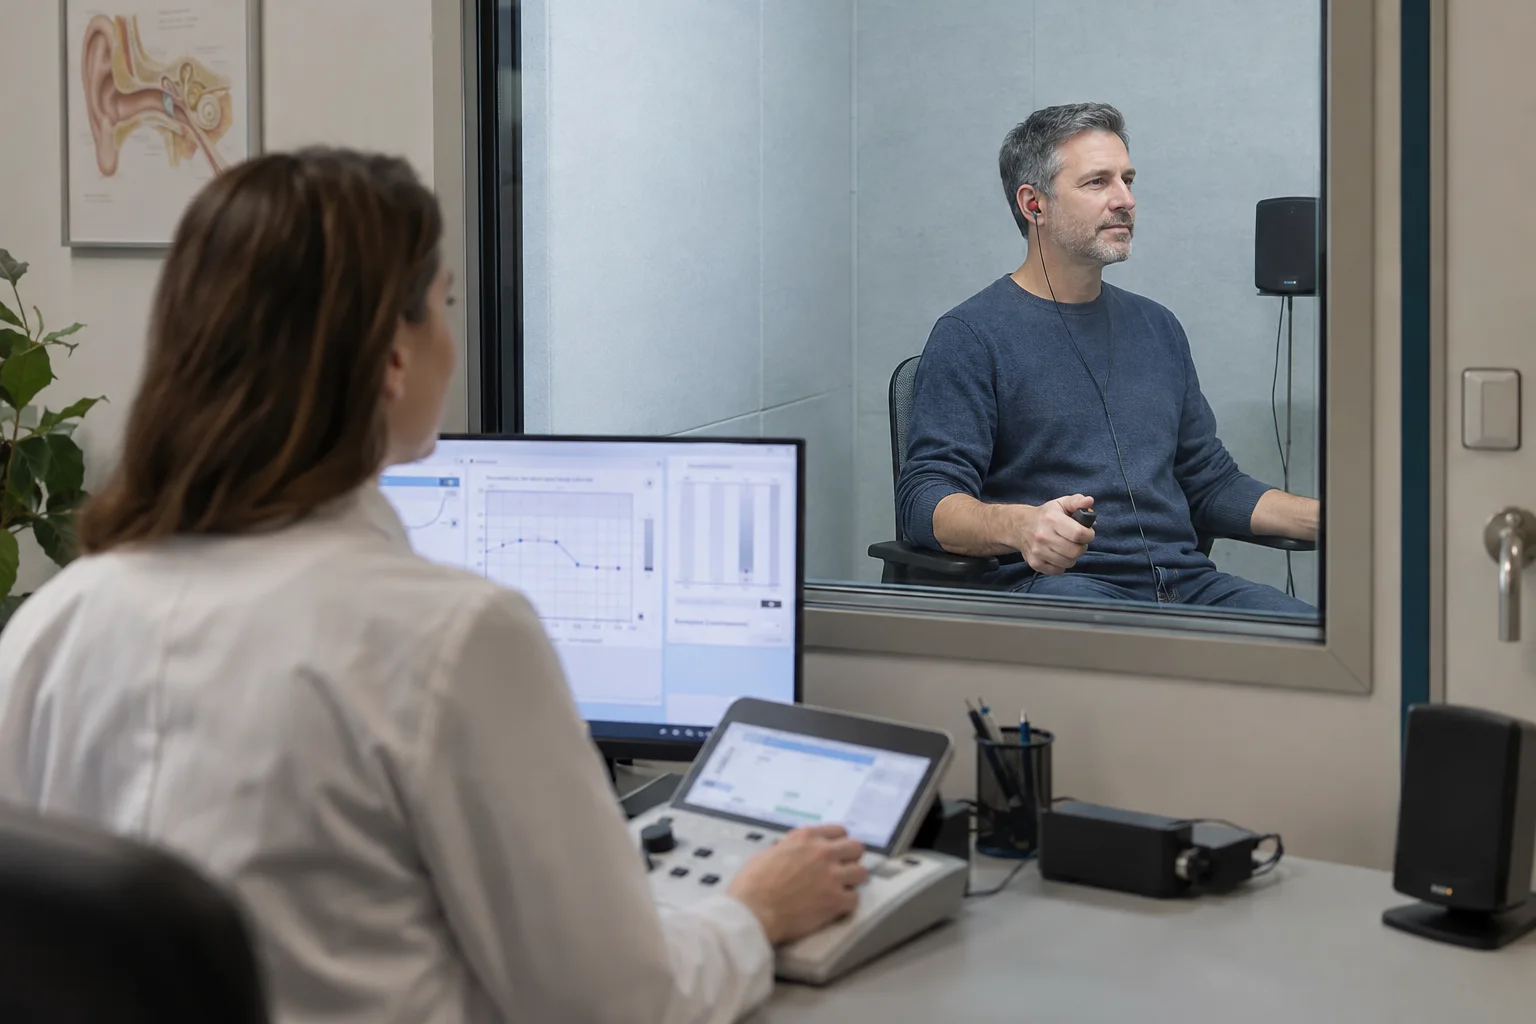
Recorded speech and competing noise are presented through earphones or loudspeakers. Some tests hold one signal steady and vary the other; some estimate the signal-to-noise relationship needed for a target score.
Ask what enters the system, what processing or measurement occurs, what output is produced and where uncertainty remains. That signal-path view is more durable than marketing names and helps identify which professional, accessory, room change or backup is actually required.
Potential advantages
The task more closely represents common communication barriers than a quiet word list and can expose a need for distance management, directional microphones or a remote microphone.
An advantage counts only when it can be demonstrated in the intended situation. Define an observable outcome before a trial: correctly understood instructions, fewer repetitions, independent setup, reliable alert detection or reduced listening effort. Record the conditions so improvement can be repeated rather than remembered vaguely.
Limits and poor-fit situations
The booth still cannot recreate every room, accent, visual cue or listening demand. Test norms and scoring differ, and fatigue, language and cognition can influence results.
Compatibility, comfort, dexterity, cognition, language, privacy, safety, service access and total ownership cost can be as important as acoustic performance. A feature that works in a quiet demonstration may fail with distance, competing speech, multiple talkers or a software change.
Worked scenario
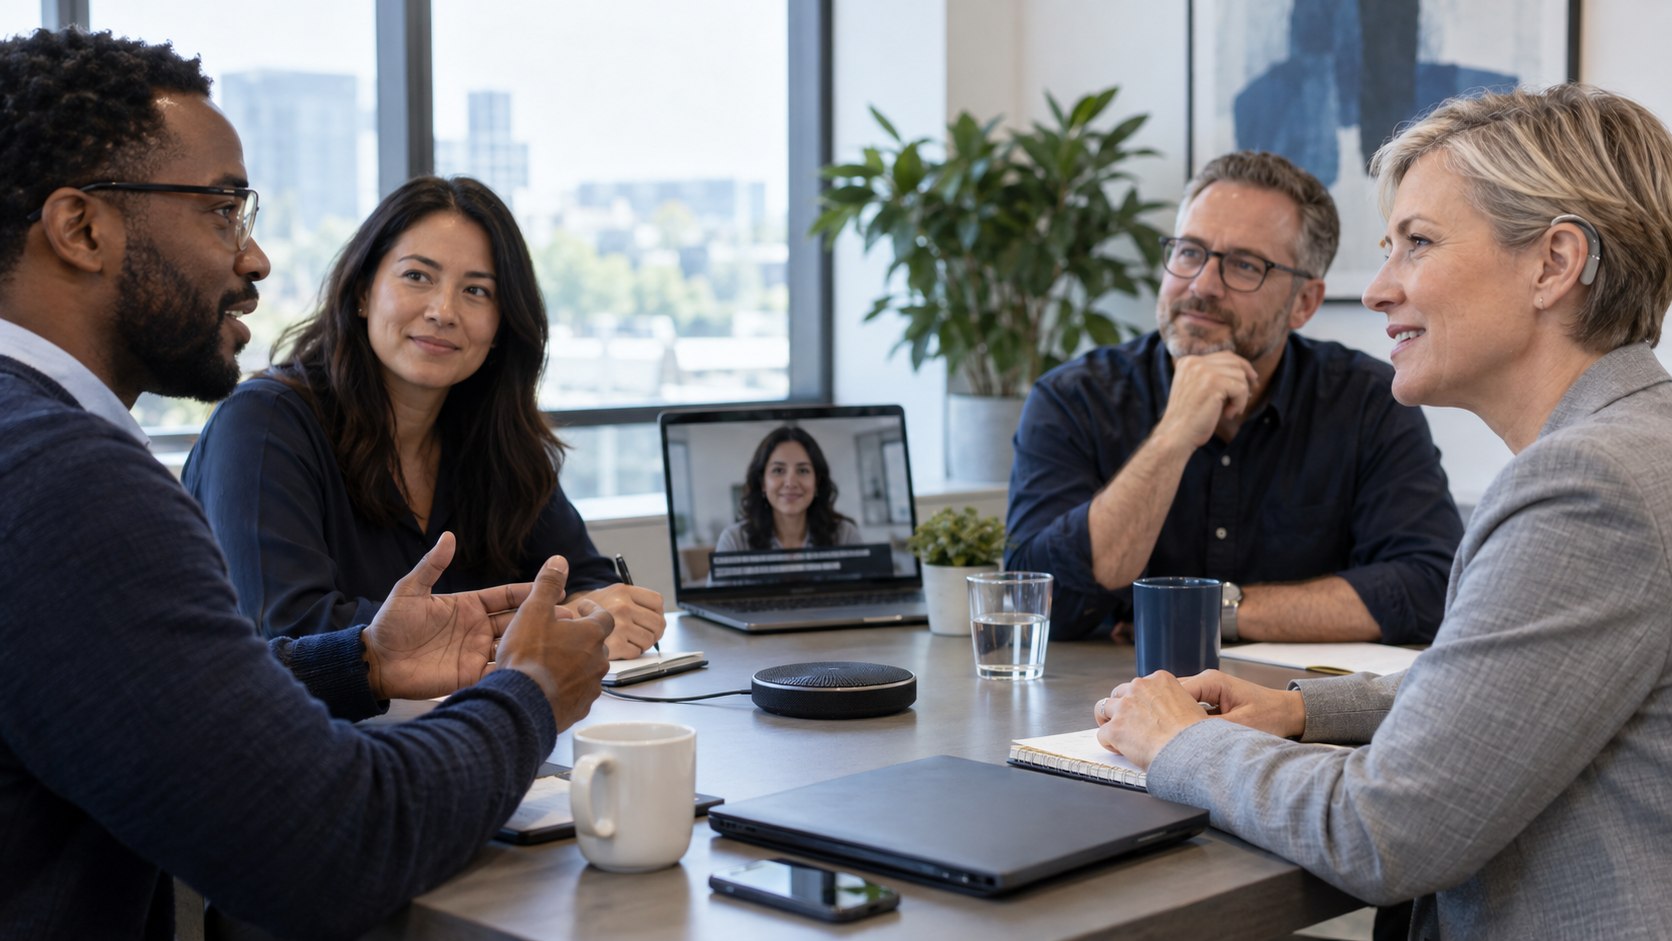
An employee has strong quiet word recognition but misses questions across a conference table. Testing shows substantial difficulty as competing speech increases. A remote microphone and meeting procedure are trialed instead of simply raising overall hearing-aid gain.
The editorial judgment is to solve the defined barrier with the least complex dependable combination, then add complexity only when the trial shows a remaining problem. A measurable trial is stronger evidence than a feature checklist or a single impressive demonstration.
A practical evaluation sequence
- Describe the task, environment and consequence of missing information.
- Check ear health, hearing information and any urgent symptoms relevant to the decision.
- Confirm exact compatibility, setup, accessories and support responsibilities.
- Trial the complete workflow, including other speakers and failure conditions.
- Verify performance with an appropriate measurement and document the baseline.
- Review benefit, limitations, maintenance, return terms and backup access.
Questions to ask
Which test and normative reference were used? Were devices verified first? What speaker arrangement and ear condition were tested? What difference would count as meaningful, and how does the result change the plan?
Request the answer in writing when it affects candidacy, safety, privacy, cost, a return deadline or continued access. Keep model names, serial numbers, settings, reports and service contacts together. For workplace or school use, identify who owns setup, training and maintenance rather than leaving those duties with the listener.
Document a repeatable trial
Create a one-page record before changing equipment or settings. Name the room or task, speaker distance, background sound, device program, accessory path and the exact information that is missed. Choose one observable measure such as correctly captured names, number of repetitions, independent connection, alert detection or listening effort on a consistent scale. Repeat the same task after the change instead of comparing two unrelated days.
Record discomfort, failures and workarounds as carefully as successes. Note who completed setup, how long it took, whether another speaker was covered and what happened when a battery, network or primary device was unavailable. A short structured record helps a clinician, employer, educator or family distinguish a real benefit from novelty. It also protects the user from keeping a costly solution that works only in the demonstration condition.
Compare claims with usable evidence
For Speech-in-Noise Testing: Measuring a Different Listening Problem, separate the category, the exact product or protocol and the individual result. A category description explains the possible mechanism; a manufacturer specification explains what one model is designed to do; a clinical or functional trial shows whether the complete setup helps this person. None of those evidence levels should silently substitute for another.
Read the conditions attached to performance numbers. Laboratory studies may use selected participants, calibrated rooms, defined noise and particular settings. Manufacturer studies can be useful when their methods and comparison conditions are visible, but they should not be converted into a promise for every listener. Independent guidance may discuss a class of technology without evaluating the newest model or software release.
Give the greatest weight to evidence that matches the decision: current official safety and compatibility instructions, an appropriate professional measurement, and a repeatable task trial. Keep the unsuccessful conditions too. Knowing that a system fails with side questions, an uncharged receiver or a particular phone is part of an honest comparison. If the only evidence is a broad claim such as “AI,” “premium,” “medical grade” or “works in noise,” ask what was measured, against what alternative and under which configuration.
Decision and safety boundary
Use the result to choose and evaluate a strategy, not to assign a percentage of hearing or promise performance in every real room.
This guide supports preparation and comparison; it does not diagnose a condition, prescribe a device or determine legal coverage. Sudden hearing change, severe pain, drainage, acute dizziness, neurologic symptoms or a foreign object in the ear requires prompt professional assessment. Verify current product instructions and official requirements because models, software and policies change.
When the answer remains uncertain, document what is known, choose the safest reversible next step and set a specific date or condition for review.
Sources and review notes
Sources were checked for this editorial update on October 12, 2026. External guidance can change; follow the linked source for the current version.
This page provides education, not an individual diagnosis, treatment plan, legal opinion or billing decision. Historical expert contribution is credited only where supported by the original project record; it does not imply review of this update.